Looking for the latest information on How Deepseek Shrank Llm Memory? We've compiled comprehensive data, records, and insights about How Deepseek Shrank Llm Memory.
Core Information
Explore the main sources for How Deepseek Shrank Llm Memory.
Recent Updates
Stay updated on How Deepseek Shrank Llm Memory's latest milestones.
DeepSeek V4 LEAKED - New Paper BROKE OpenAI Scaling - Conditional Memory via Scalable Lookup
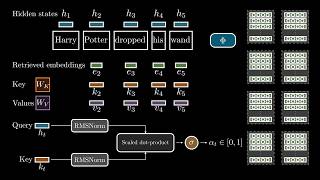
How DeepSeek Rewrote the Transformer [MLA]
DeepSeek's V4.1-Flash Shrunk Its Memory 437X
DeepSeek's MLA Explained: The AI Breakthrough That Solves the KV Cache Memory Problem (2026)
How DeepSeek Solved the 1 Million Token RAM Problem (DeepSeek-V4.1-Flash)
How DeepSeek Cuts AI Memory by 32× | Multi-Head Latent Attention (MLA) Explained
DeepSeek just solved LLM inferencing (again)
DeepSeek Is Back with Engram: Built‑In Memory for LLMs: With Demo
Expert Insights
Data is compiled from public records and verified media reports.
Last Updated: October 3, 2026
Summary
For 2026, How Deepseek Shrank Llm Memory remains one of the most talked-about information profiles. Check back for the latest updates.
Disclaimer: Disclaimer: All information is compiled from publicly available data, media reports, and analysis. Actual details may vary.
Summary
What the KV cache is, why it takes so much GPU What if AI models could finally remember what's important and forget what's not—just the human brain? In this video, we dive ... Become AI Researcher - skool.com/become-ai-researcher-2669/about arxiv - arxiv.org/pdf/2601.07372 ... Thanks to KiwiCo for sponsoring today's video! Go to kiwico.com/welchlabs and use code WELCHLABS for 50% off ... A deep dive into Causal Encoder Decoder architectures,